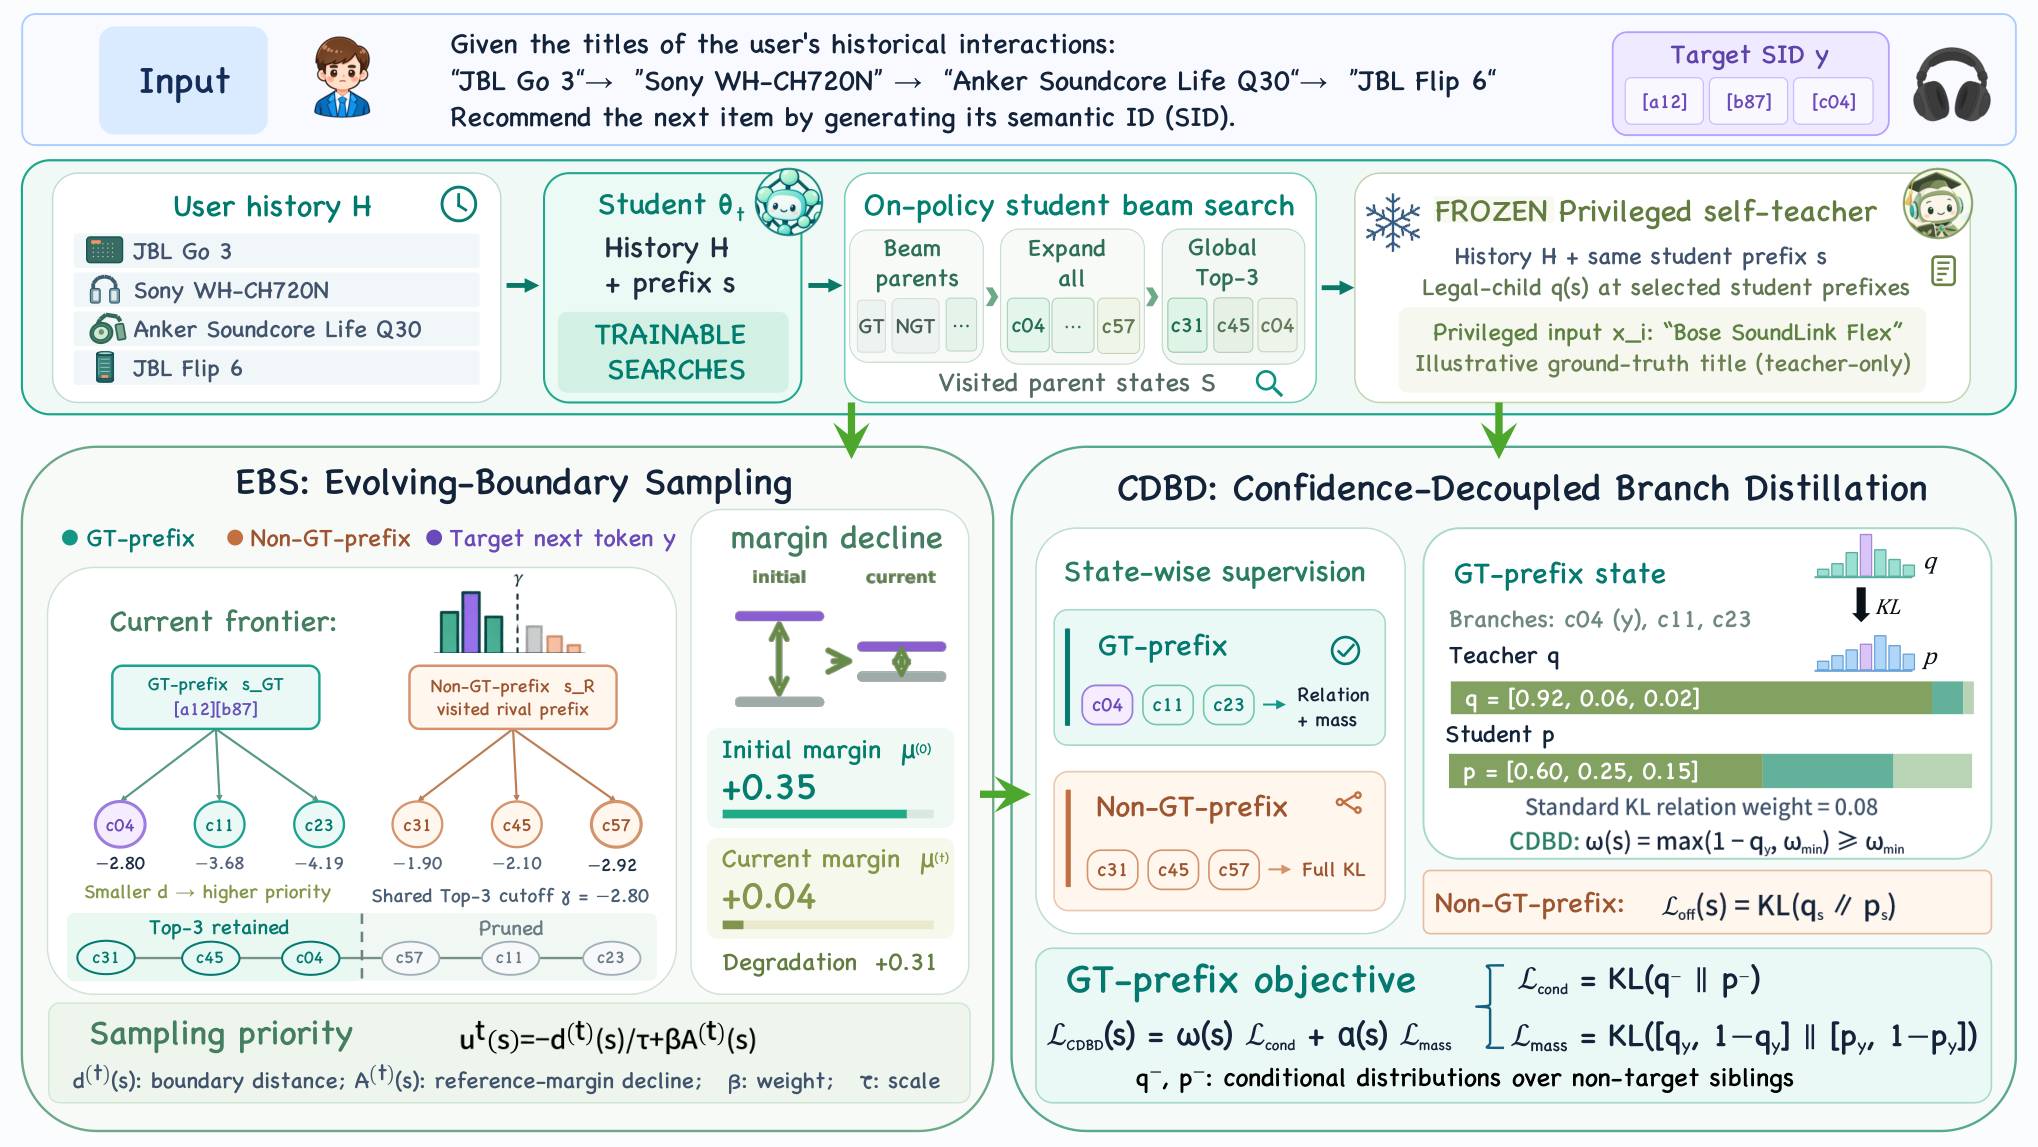
@article{guo2026saopsd,title={Search-Aware On-Policy Self-Distillation with Sibling Alignment for Generative Recommendation},author={Guo, Rongfeng and Zhuang, Zhuang and Dai, Ji and Zhao, Peng and Li, Shijie and Chen, Jie and Long, Teng and Hu, Vincent Tao and Pan, Fei},year={2026},month=nov,booktitle={arXiv},status={preprint},}
arXiv
GramLoop: Training-Free Gram-Gated Replay for Robust Dense Prediction
Yang Chen, Canyu Shen, Xinzhe Rao, Yuanyi Yan, Yunlu Chen, Meng Tang, Teng Long, and Vincent Tao Hu
@article{chen2026gramloop,title={{GramLoop}: Training-Free Gram-Gated Replay for Robust Dense Prediction},author={Chen, Yang and Shen, Canyu and Rao, Xinzhe and Yan, Yuanyi and Chen, Yunlu and Tang, Meng and Long, Teng and Hu, Vincent Tao},year={2026},booktitle={arXiv},status={preprint},}
arXiv
Training-Free Hidden-State Refinement for Flow-Matching Image Generators
Yuanyi Yan, Xinzhe Rao, Canyu Shen, Yang Chen, Yunlu Chen, Meng Tang, Teng Long, and Vincent Tao Hu
@article{yan2026hiddenstate,title={Training-Free Hidden-State Refinement for Flow-Matching Image Generators},author={Yan, Yuanyi and Rao, Xinzhe and Shen, Canyu and Chen, Yang and Chen, Yunlu and Tang, Meng and Long, Teng and Hu, Vincent Tao},year={2026},booktitle={arXiv},status={preprint},}
arXiv
From State to Action: OODA-Tool for Reliable Multi-Turn Tool Use
Rongfeng Guo, Yinxuan Huang, Yusen Wu, Maoqing Zhong, Yunlu Chen, Meng Tang, Teng Long, and Vincent Tao Hu
@article{guo2026oodatool,title={From State to Action: {OODA-Tool} for Reliable Multi-Turn Tool Use},author={Guo, Rongfeng and Huang, Yinxuan and Wu, Yusen and Zhong, Maoqing and Chen, Yunlu and Tang, Meng and Long, Teng and Hu, Vincent Tao},year={2026},booktitle={arXiv},status={preprint},}
IJCV
Diversifying Similar Subjects for Text-to-image Synthesis with Self-Cross Diffusion Guidance and Reward
Weimin Qiu, Jieke Wang, Zhining Gu, Vincent Tao Hu, and Meng Tang
@article{qiu2026diversifying,title={Diversifying Similar Subjects for Text-to-image Synthesis with Self-Cross Diffusion Guidance and Reward},author={Qiu, Weimin and Wang, Jieke and Gu, Zhining and Hu, Vincent Tao and Tang, Meng},year={2026},journal={International Journal of Computer Vision},}
CVPR
Guiding Token-Sparse Diffusion Models
Felix Krause, Stefan Andreas Baumann, Johannes Schusterbauer, Olga Grebenkova, Ming Gui, Vincent Tao Hu, and Björn Ommer
@inproceedings{krause2026guiding,title={Guiding Token-Sparse Diffusion Models},author={Krause, Felix and Baumann, Stefan Andreas and Schusterbauer, Johannes and Grebenkova, Olga and Gui, Ming and Hu, Vincent Tao and Ommer, Björn},year={2026},booktitle={CVPR},repostar={CompVis/tread}}
ICLR
Purrception: Variational Flow Matching for Vector-Quantized Image Generation
Răzvan-Andrei Matișan, Vincent Tao Hu, Grigory Bartosh, Björn Ommer, Cees G.M. Snoek, Max Welling, Jan-Willem van de Meent, Mohammad Mahdi Derakhshani, and Floor Eijkelboom
@inproceedings{maticsan2026purrception,title={Purrception: Variational Flow Matching for Vector-Quantized Image Generation},author={Matișan, Răzvan-Andrei and Hu, Vincent Tao and Bartosh, Grigory and Ommer, Björn and Snoek, Cees G.M. and Welling, Max and van de Meent, Jan-Willem and Derakhshani, Mohammad Mahdi and Eijkelboom, Floor},year={2026},booktitle={ICLR},}
TPAMI
Diffusion Models and Representation Learning: A Survey
Michael Fuest, Pingchuan Ma, Ming Gui, Johannes Fischer, Vincent Tao Hu, and Björn Ommer
In T-PAMI, 2026
The interplay between diffusion models and representation learning
@inproceedings{diffusion_rl_survey,title={Diffusion Models and Representation Learning: A Survey},author={Fuest, Michael and Ma, Pingchuan and Gui, Ming and Fischer, Johannes and Hu, Vincent Tao and Ommer, Björn},year={2026},note={The interplay between diffusion models and representation learning},booktitle={T-PAMI},repostar={dongzhuoyao/Diffusion-Representation-Learning-Survey-Taxonomy}}
2025
ICCV
TREAD: Token Routing for Efficient Architecture-agnostic Diffusion Training
Felix Krause, Timy Phan, Ming Gui, Stefan Andreas Baumann, Vincent Tao Hu, and Björn Ommer
@inproceedings{tread,title={TREAD: Token Routing for Efficient Architecture-agnostic Diffusion Training},author={Krause, Felix and Phan, Timy and Gui, Ming and Baumann, Stefan Andreas and Hu, Vincent Tao and Ommer, Björn},year={2025},note11={Skipping layers to boost training convergence},booktitle={ICCV},highlight111={Oral},repostar={CompVis/tread},highlight={Oral}}
ICCV
Stochastic Interpolants for Revealing Stylistic Flows across the History of Art
Pingchuan Ma, Ming Gui, Johannes Schusterbauer, Xiaopei Yang, Olga Grebenkova, Vincent Tao Hu, and Björn Ommer
@inproceedings{artflow,title={Stochastic Interpolants for Revealing Stylistic Flows across the History of Art},author={Ma, Pingchuan and Gui, Ming and Schusterbauer, Johannes and Yang, Xiaopei and Grebenkova, Olga and Hu, Vincent Tao and Ommer, Björn},year={2025},booktitle={ICCV},repostar={CompVis/Art-fm}}
CVPR
Continuous, Subject-Specific Attribute Control in T2I Models by Identifying Semantic Directions
Stefan Andreas Baumann, Felix Krause, Michael Neumayr, Nick Stracke, Vincent Tao Hu, and Björn Ommer
@inproceedings{baumann2024attributecontrol,title={{C}ontinuous, {S}ubject-{S}pecific {A}ttribute {C}ontrol in {T}2{I} {M}odels by {I}dentifying {S}emantic {D}irections},author={Baumann, Stefan Andreas and Krause, Felix and Neumayr, Michael and Stracke, Nick and Hu, Vincent Tao and Ommer, Björn},year={2025},note={Prompt Editing in T2I models},booktitle={CVPR},repostar={CompVis/attribute-control}}
arXiv
MaskFlow: Discrete Flows for Flexible and Efficient Long Video Generation
@inproceedings{maskflow,title={MaskFlow: Discrete Flows for Flexible and Efficient Long Video Generation},author={Fuest, Michael and Hu, Vincent Tao and Ommer, Björn},year={2025},booktitle={arXiv},preview1111={./mask.jpg},repostar={CompVis/maskflow},status={preprint}}
ICLR
ToddlerDiffusion: Flash Interpretable Controllable Diffusion Model
Eslam Mohamed BAKR, Liangbing Zhao, Vincent Tao Hu, Matthieu Cord, Patrick Perez, and Mohamed Elhoseiny
@inproceedings{ToddlerDiffusion,title={ToddlerDiffusion: Flash Interpretable Controllable Diffusion Model},author={BAKR, Eslam Mohamed and Zhao, Liangbing and Hu, Vincent Tao and Cord, Matthieu and Perez, Patrick and Elhoseiny, Mohamed},year={2025},booktitle={ICLR},repostar={toddlerdiffusion/code}}
AAAI
DepthFM: Fast Monocular Depth Estimation with Flow Matching
Ming Gui, Johannes S. Fischer, Ulrich Prestel, Pingchuan Ma, Dmytro Kotovenko, Olga Grebenkova, Stefan A. Baumann, Vincent Tao Hu, and Björn Ommer
In AAAI, 2025
An exploration of flow matching for blazing fast and zero-shot depth estimation
@inproceedings{depthfm,title={DepthFM: Fast Monocular Depth Estimation with Flow Matching},author={Gui, Ming and Fischer, Johannes S. and Prestel, Ulrich and Ma, Pingchuan and Kotovenko, Dmytro and Grebenkova, Olga and Baumann, Stefan A. and Hu, Vincent Tao and Ommer, Björn},year={2025},note={An exploration of flow matching for blazing fast and zero-shot depth estimation},booktitle={AAAI},highlight={Oral},repostar={CompVis/depth-fm}}
AAAI
Does VLM Classification Benefit from LLM Description Semantics?
Pingchuan Ma, Lennart Rietdorf, Dmytro Kotovenko, Vincent Tao Hu, and Björn Ommer
@inproceedings{fundel2025distilldift,title={Distillation of Diffusion Features for Semantic Correspondence},author={Fundel, Frank and Schusterbauer, Johannes and Hu, Vincent Tao and Ommer, Björn},year={2025},note={},booktitle={WACV},repostar={CompVis/DistillDIFT}}
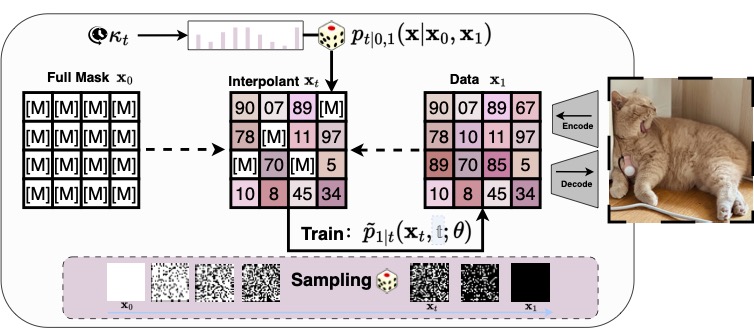
@inproceedings{hu24mask,title={[MASK] is All You Need},author={Hu, Vincent Tao and Ommer, Björn},year={2024},booktitle={arXiv},repostar={CompVis/discrete-interpolants},status={preprint}}
arXiv
Scaling Image Tokenizers with Grouped Spherical Quantization
Jiangtao Wang, Zhen Qin, Yifan Zhang, Vincent Tao Hu, Björn Ommer, Rania Briq, and Stefan Kesselheim
@article{wang2024scaling,title={Scaling Image Tokenizers with Grouped Spherical Quantization},author={Wang, Jiangtao and Qin, Zhen and Zhang, Yifan and Hu, Vincent Tao and Ommer, Bj{\"o}rn and Briq, Rania and Kesselheim, Stefan},booktitle={arXiv},year={2024},note={},repostar={HelmholtzAI-FZJ/flex_gen},status={preprint}}
ECCV
ZigMa: A DiT-style Zigzag Mamba Diffusion Model
Vincent Tao Hu, Stefan Andreas Baumann, Ming Gui, Olga Grebenkova, Pingchuan Ma, Johannes Fischer, and Björn Ommer
@inproceedings{hu2024zigmaa,title={ZigMa: A DiT-style Zigzag Mamba Diffusion Model},author={Hu, Vincent Tao and Baumann, Stefan Andreas and Gui, Ming and Grebenkova, Olga and Ma, Pingchuan and Fischer, Johannes and Ommer, Björn},year={2024},note={a DiT-style Mamba-based diffusion models },booktitle={ECCV},repostar={CompVis/zigma}}
ECCV
Boosting Latent Diffusion with Flow Matching
Johannes S. Fischer, Ming Gui, Pingchuan Ma, Nick Stracke, Stefan A. Baumann, Vincent Tao Hu, and Björn Ommer
@inproceedings{fischer2023boosting,title={Boosting Latent Diffusion with Flow Matching},author={Fischer, Johannes S. and Gui, Ming and Ma, Pingchuan and Stracke, Nick and Baumann, Stefan A. and Hu, Vincent Tao and Ommer, Björn},year={2024},note={flow matching for super-resolution},booktitle={ECCV},highlight={Oral},repostar={CompVis/fm-boosting}}
arXiv
Guided Flow Vision Transformer from Self-Supervised Diffusion Features
Vincent Tao Hu, Yunlu Chen, Mathilde Caron, Yuki M. Asano, Cees G.M. Snoek, and Björn Ommer
@inproceedings{sgfm,title={Guided Flow Vision Transformer from Self-Supervised Diffusion Features},author={Hu, Vincent Tao and Chen, Yunlu and Caron, Mathilde and Asano, Yuki M. and Snoek, Cees G.M. and Ommer, Björn},year={2024},note={},booktitle={arXiv},repostar={dongzhuoyao/sgfm},status={preprint}}
arXiv
Motion Flow Matching for Human Motion Synthesis and Editing
Vincent Tao Hu, Wenzhe Yin, Pingchuan Ma, Yunlu Chen, Basura Fernando, Yuki M. Asano, Efstratios Gavves, Pascal Mettes, Björn Ommer, and Cees G.M. Snoek
@inproceedings{motionfm,title={Motion Flow Matching for Human Motion Synthesis and Editing},author={Hu, Vincent Tao and Yin, Wenzhe and Ma, Pingchuan and Chen, Yunlu and Fernando, Basura and Asano, Yuki M. and Gavves, Efstratios and Mettes, Pascal and Ommer, Björn and Snoek, Cees G.M.},year={2024},note1={},booktitle={arXiv},repostar={dongzhuoyao/motionfm},status={preprint}}
arXiv
Training Class-Imbalanced Diffusion Model Via Overlap Optimization
Divin Yan, Lu Qi, Vincent Tao Hu, Ming-Hsuan Yang, and Meng Tang
@inproceedings{constrastivediffusion,title={Training Class-Imbalanced Diffusion Model Via Overlap Optimization},author={Yan, Divin and Qi, Lu and Hu, Vincent Tao and Yang, Ming-Hsuan and Tang, Meng},year={2024},note={},booktitle={arXiv},status={preprint}}
AAAI
Latent Space Editing in Transformer-based Flow Matching
Vincent Tao Hu, David W Zhang, Pascal Mettes, Meng Tang, Deli Zhao, and Cees G.M. Snoek
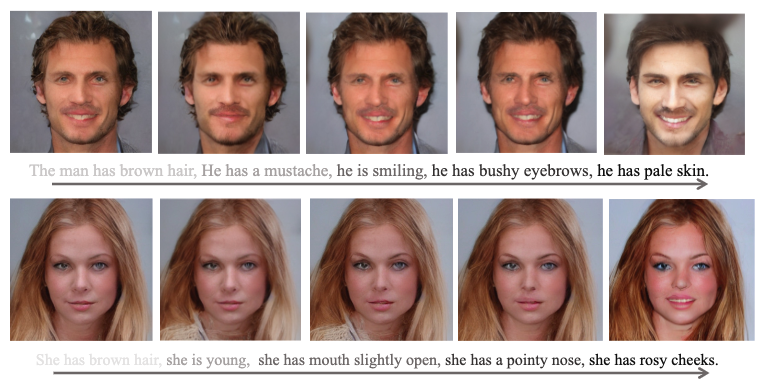
@inproceedings{hulfm,title={Latent Space Editing in Transformer-based Flow Matching},author={Hu, Vincent Tao and Zhang, David W and Mettes, Pascal and Tang, Meng and Zhao, Deli and Snoek, Cees G.M.},year={2024},note={},booktitle={AAAI},repostar={dongzhuoyao/uspace}}
EACL
Flow Matching for Conditional Text Generation in a Few Sampling Steps
Vincent Tao Hu, Di Wu, Yuki M. Asano, Pascal Mettes, Basura Fernando, Björn Ommer, and Cees G.M. Snoek
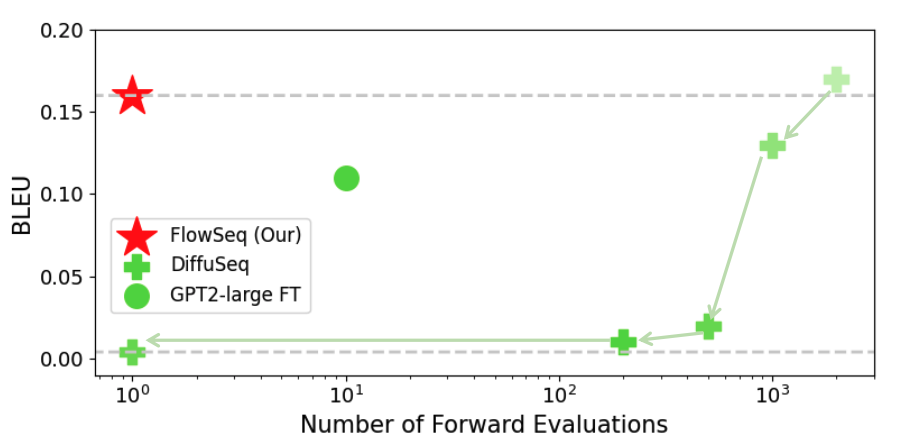
@inproceedings{huflowseq,title={Flow Matching for Conditional Text Generation in a Few Sampling Steps},author={Hu, Vincent Tao and Wu, Di and Asano, Yuki M. and Mettes, Pascal and Fernando, Basura and Ommer, Björn and Snoek, Cees G.M.},year={2024},booktitle={EACL},note={Flow Matching for text generation},selectedddd={true},repostar={dongzhuoyao/flowseq}}
2023
CVPR
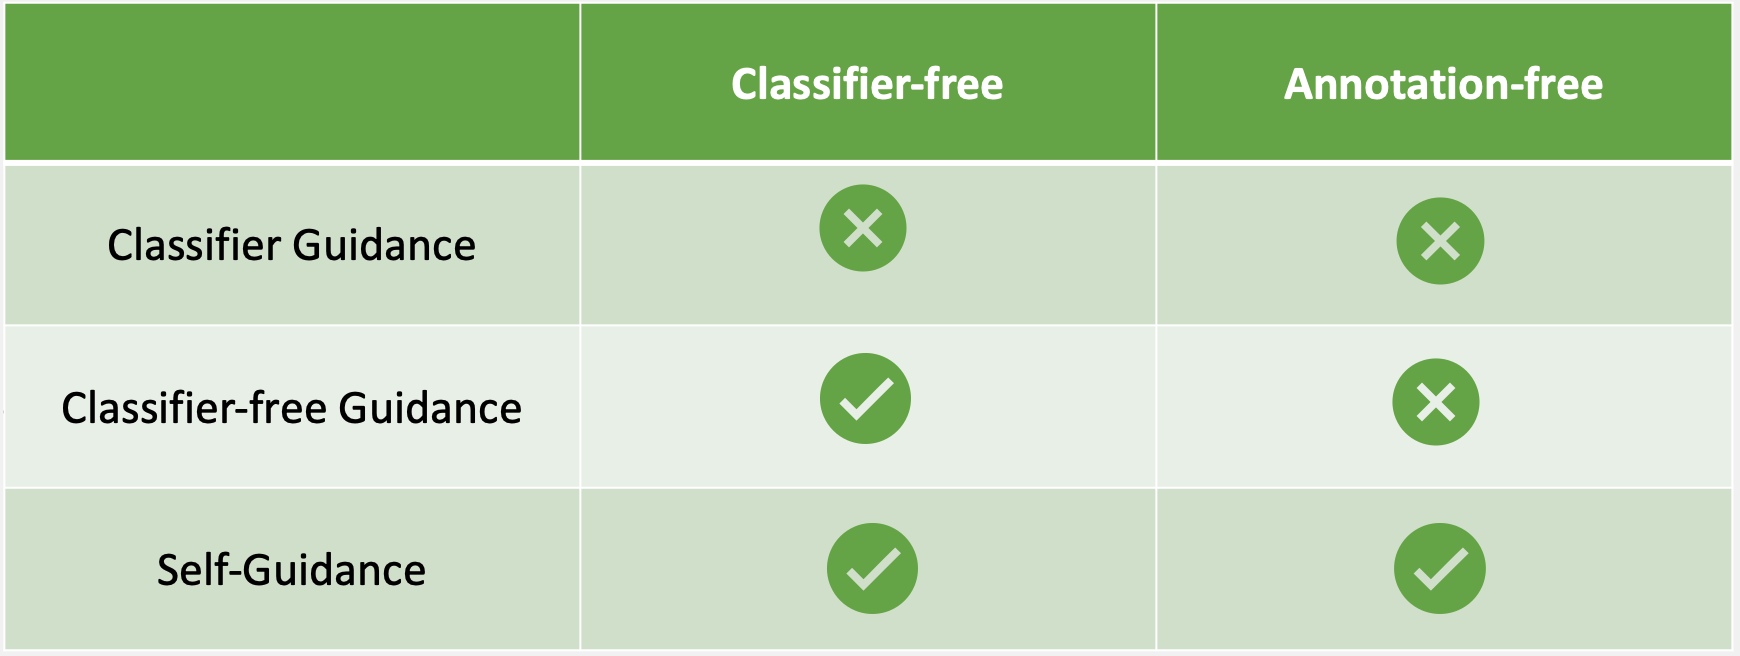
Self-Guided Diffusion Models
Tao Hu*, David W Zhang*, Yuki M. Asano, Gertjan J. Burghouts, and Cees G.M. Snoek
In CVPR, 2023
A bridge between the community of self-supervised learning and diffusion models. Short version to appear in NeurIPS 2022 Workshop on Score-Based Methods and NeurIPS 2022 Workshop Self-Supervised Learning Theory and Practice.
@inproceedings{hu2022selfguided,title={Self-Guided Diffusion Models},author={Hu*, Tao and Zhang*, David W and Asano, Yuki M. and Burghouts, Gertjan J. and Snoek, Cees G.M.},year={2023},booktitle={CVPR},note={A bridge between the community of self-supervised learning and diffusion models. Short version to appear in NeurIPS 2022 Workshop on Score-Based Methods and NeurIPS 2022 Workshop Self-Supervised Learning Theory and Practice.},repostar={dongzhuoyao/self-guided-diffusion-models}}
2022
WACV
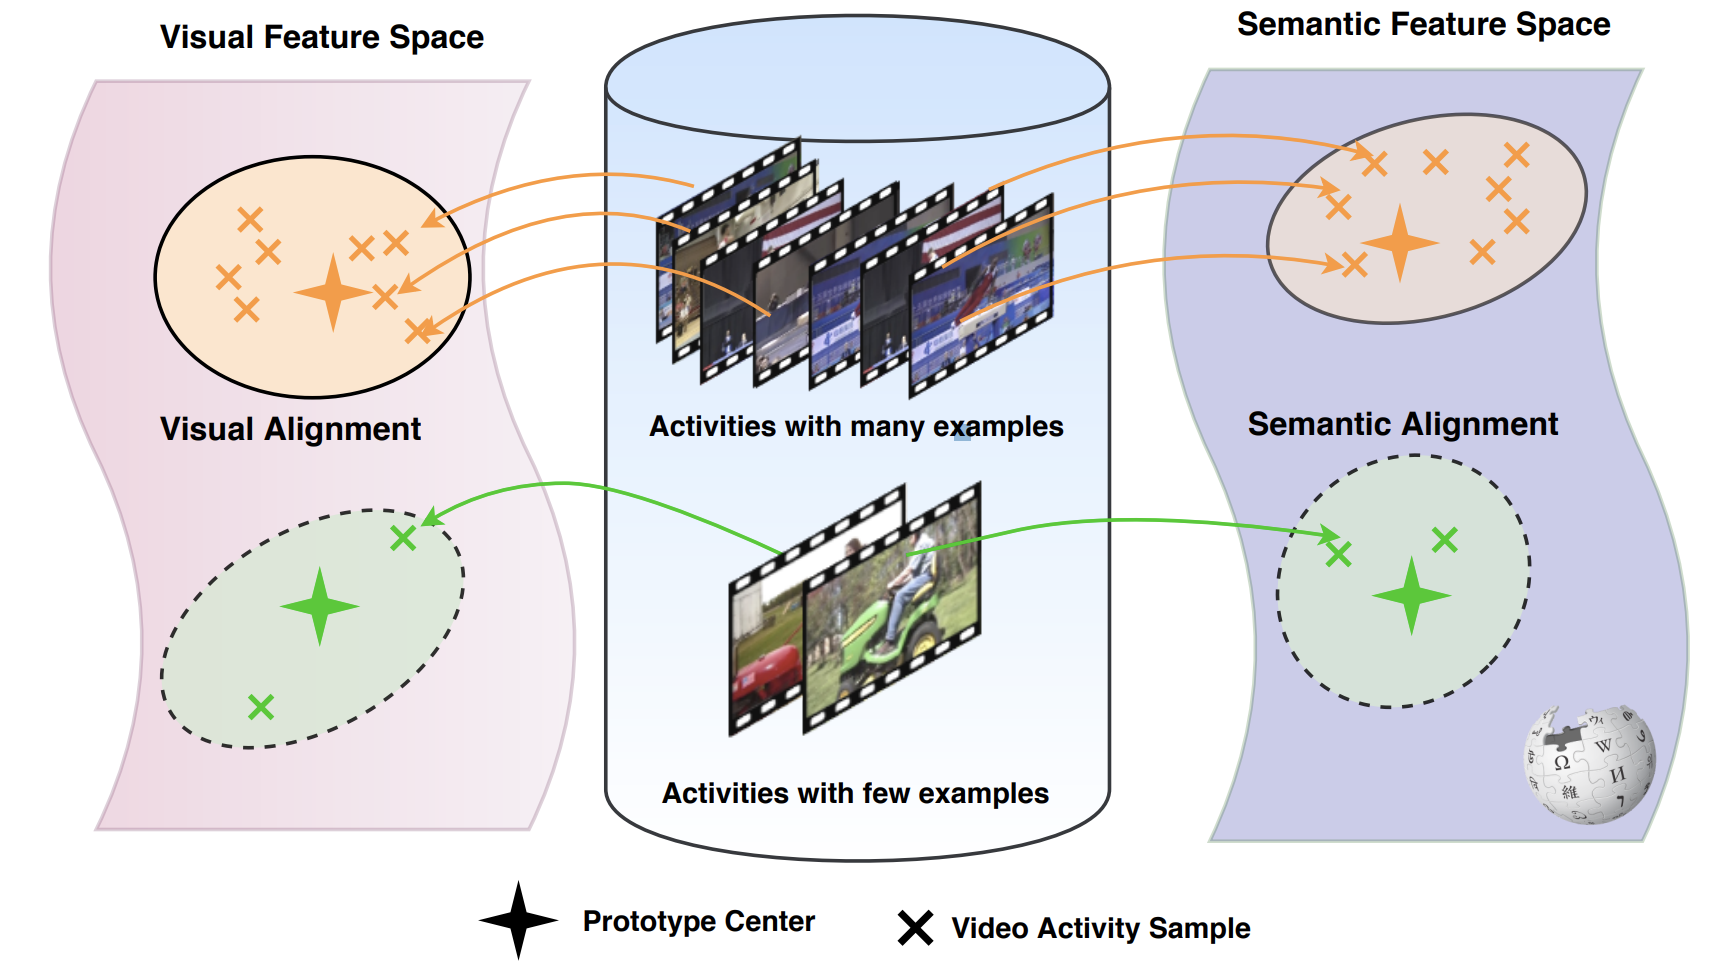
Self-Supervised Video Representation Learning with Cross-Stream Prototypical Contrasting
Martine Toering, Ioannis Gatopoulos, Maarten Stol, and Vincent Tao Hu
In WACV, 2022
Improve video representation by contrasting prototypical features.
@inproceedings{toering2022self,title={Self-Supervised Video Representation Learning with Cross-Stream Prototypical Contrasting},author={Toering, Martine and Gatopoulos, Ioannis and Stol, Maarten and Hu, Vincent Tao},booktitle={WACV},year={2022},note={Improve video representation by contrasting prototypical features.},repostar={martinetoering/ViCC}}
2020
ECCV
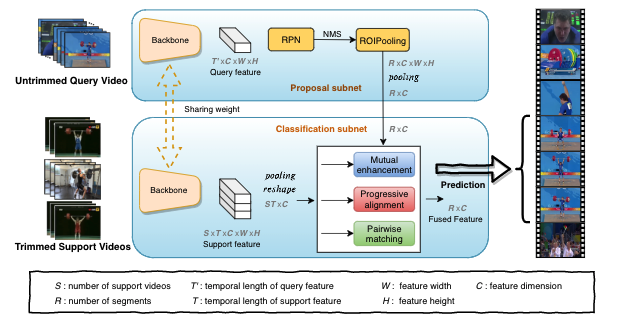
Localizing the Common Action Among a Few Videos
Pengwan Yang*, Tao Hu*, Pascal Mettes, and Cees G.M. Snoek
In ECCV, 2020
Localizing the temporal extent of an action in a long untrimmed video by attention techniques.
@inproceedings{YangECCV20,author={Yang*, Pengwan and Hu*, Tao and Mettes, Pascal and Snoek, Cees G.M.},title={Localizing the Common Action Among a Few Videos},booktitle={ECCV},year={2020},note={Localizing the temporal extent of an action in a long untrimmed video by attention techniques.},repostar={PengWan-Yang/commonLocalization}}
ECCV
Pointmixup: Augmentation for point clouds
Yunlu Chen*, Tao Hu*, Efstratios Gavves, Thomas Mensink, Pascal Mettes, Pengwan Yang, and Cees G.M. Snoek
In ECCV, 2020
A simple augmentation method based on MixUp to boost the performance on related tasks of point cloud.
@inproceedings{chen2020pointmixup,title={Pointmixup: Augmentation for point clouds},author={Chen*, Yunlu and Hu*, Tao and Gavves, Efstratios and Mensink, Thomas and Mettes, Pascal and Yang, Pengwan and Snoek, Cees G.M.},booktitle={ECCV},highlight={Spotlight},year={2020},note={A simple augmentation method based on MixUp to boost the performance on related tasks of point cloud.},repostar={yunlu-chen/PointMixup}}
2019
AAAI
Attention-based Multi-Context Guiding for Few-Shot Semantic Segmentation
Tao Hu, Pengwan Yang, Chiliang Zhang, Gang Yu, Yadong Mu, and Cees G.M. Snoek
In AAAI, 2019
Solve the few-shot segmentation problem by applying attention in multi-scales.
@inproceedings{tao2018fss,title={Attention-based Multi-Context Guiding for Few-Shot Semantic Segmentation},author={Hu, Tao and Yang, Pengwan and Zhang, Chiliang and Yu, Gang and Mu, Yadong and Snoek, Cees G.M.},booktitle={AAAI},highlight={Spotlight},year={2019},note={Solve the few-shot segmentation problem by applying attention in multi-scales.},}
ICCV
SILCO: Show a Few Images, Localize the Common Object
Tao Hu, Pascal Mettes, Jia-Hong Huang, and Cees G.M. Snoek
In ICCV, 2019
Design a graph network and apply attention on them to solve the problem of common object localization.
@inproceedings{silco2019,title={SILCO: Show a Few Images, Localize the Common Object},author={Hu, Tao and Mettes, Pascal and Huang, Jia-Hong and Snoek, Cees G.M.},booktitle={ICCV},year={2019},note={Design a graph network and apply attention on them to solve the problem of common object localization.},repostar={dongzhuoyao/silco_}}








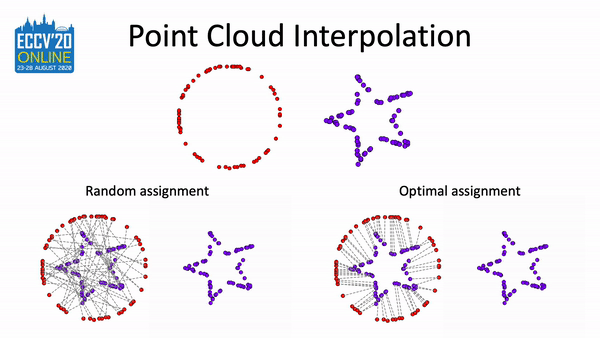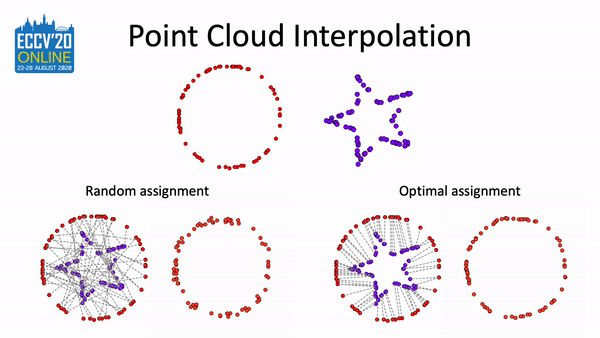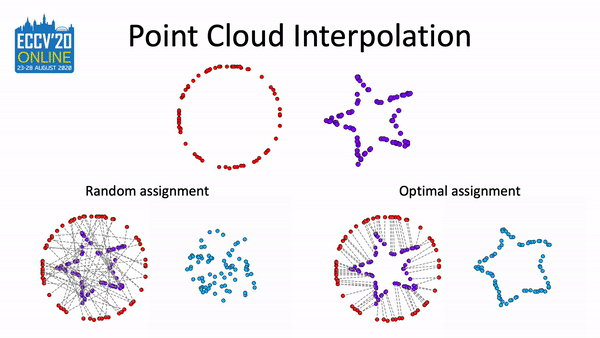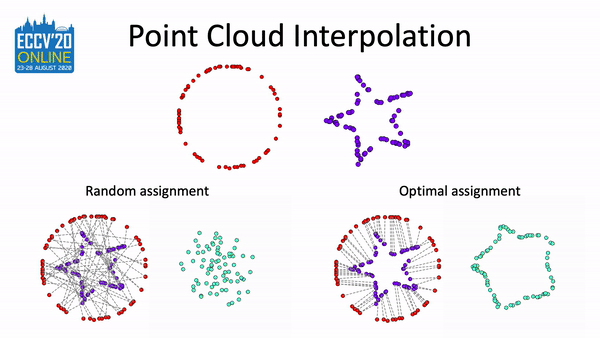 Pointmixup: Augmentation for point cloudsIn ECCV, 2020A simple augmentation method based on MixUp to boost the performance on related tasks of point cloud.


 Attention-based Multi-Context Guiding for Few-Shot Semantic SegmentationIn AAAI, 2019Solve the few-shot segmentation problem by applying attention in multi-scales.

